




Real Fetch resume examples, and how to write yours
Templates show what a resume could look like; these show what got through. Below: three of them in full, each with what it does well and a text version you can read, then a step-by-step guide to writing a resume for Fetch, built from all 3: how to write bullet points.
Fetch resume examples, and what they do well
1. Software Engineer resume that passed Fetch, DoorDash and 4 more
Real resumeVerifiedPassed the screen atFetch
DoorDash
Aritzia
Bilt Rewards+2 more
Bachelor's in Computer Science, University
Show resumeHide resume
 View full size
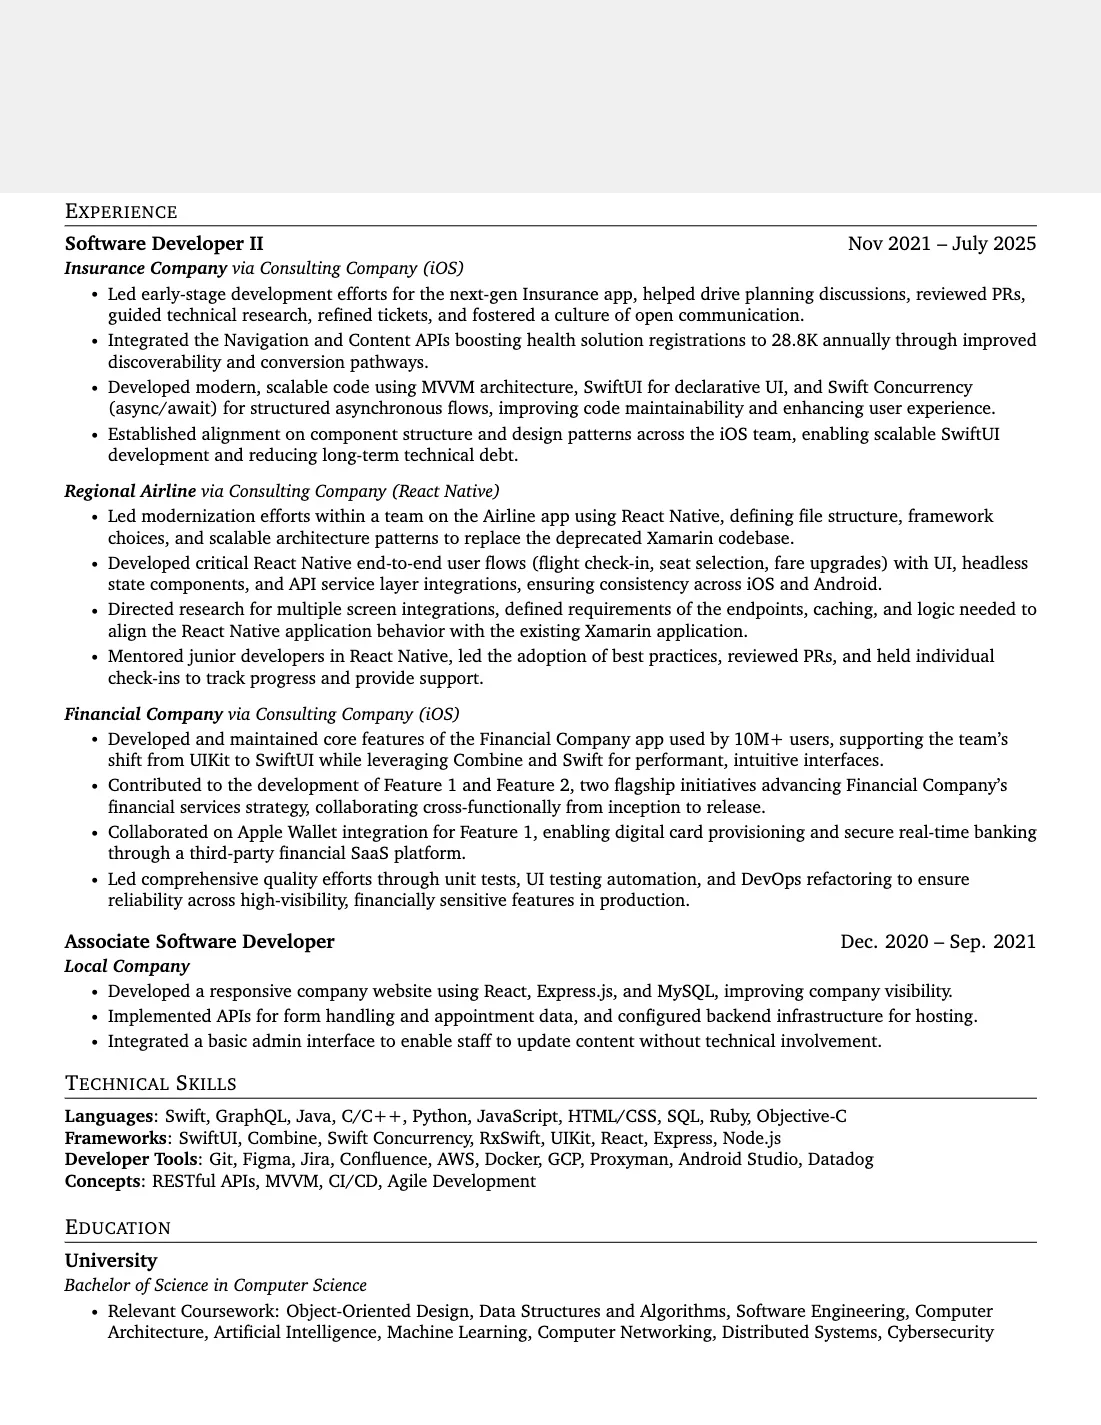
Uploaded by its owner. Contact details redacted. What this resume does well
- Specific skillsIt names 32 languages and tools, including Swift, GraphQL and Java.
- One pageEverything fits on one page.
2. Software Engineer new grad resume that passed Fetch and Fidelity
Real resumePassed the screen atFidelity
Master's in Computer Science, Rochester Institute Of Technology, 2025
Show resumeHide resume
 View full size
Uploaded by its owner. Contact details redacted. What this resume does well
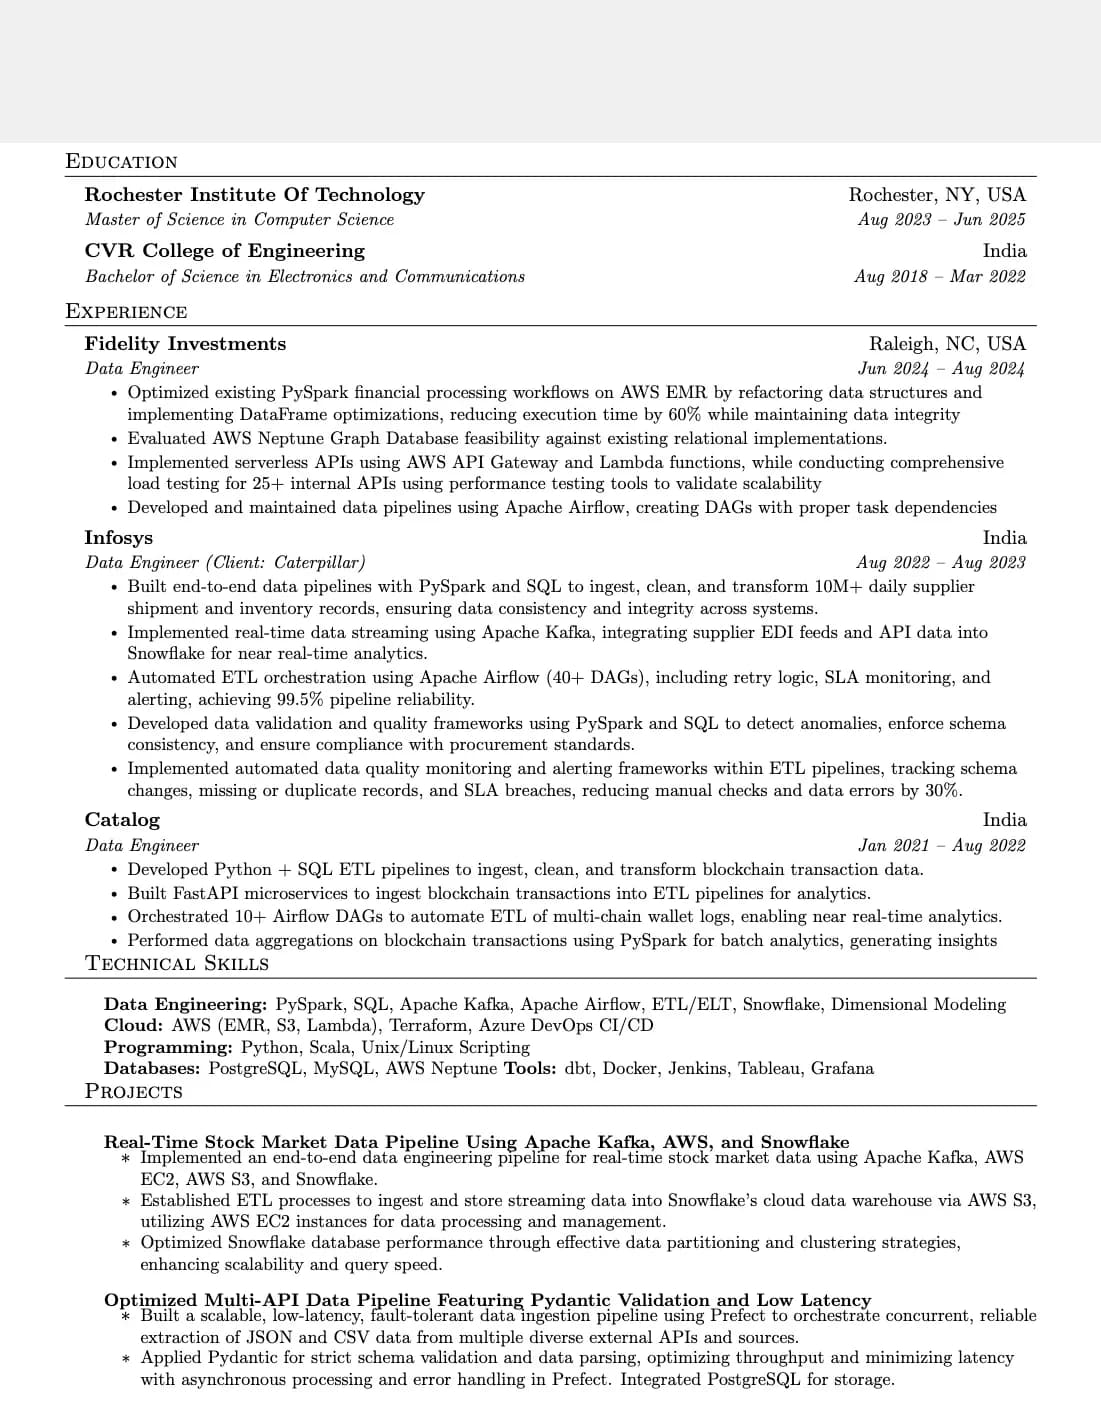
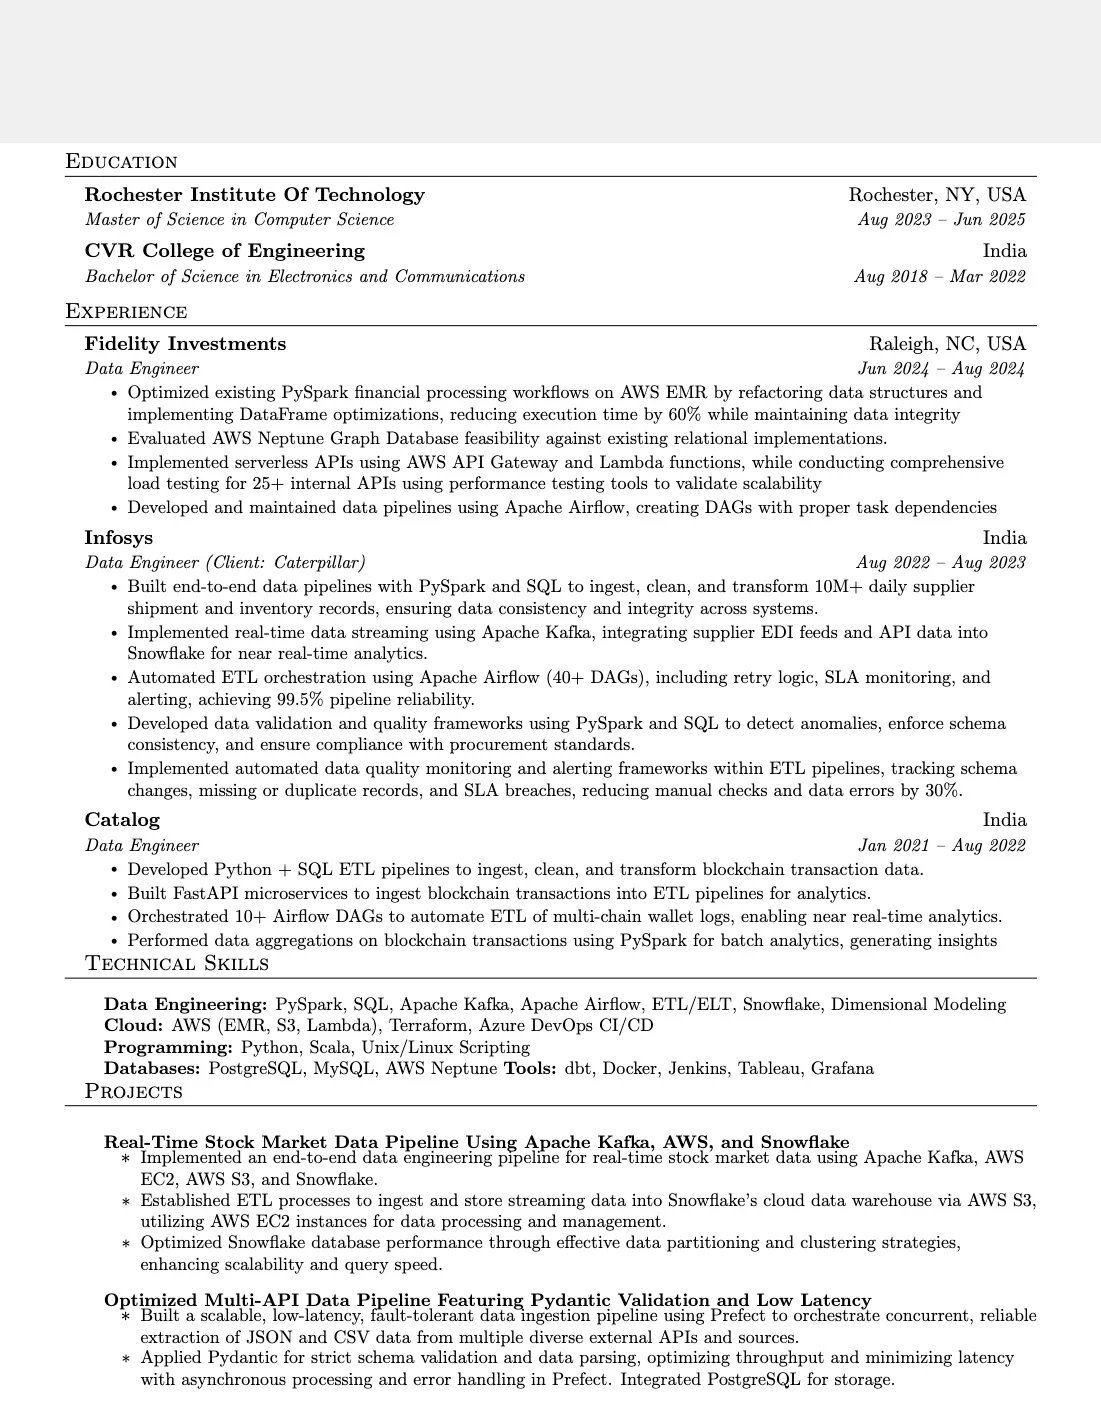
- Education firstIt opens with education, the first thing a screener checks on a student resume.
- A projects sectionWith no internship listed, its projects section does the work of an experience section.
- Specific skillsIt names 21 languages and tools, including PySpark, SQL and Apache Kafka.
- One pageEverything fits on one page.
Read this resume as text
Education
Rochester Institute Of Technology Rochester, NY, USA
Master of Science in Computer Science Aug 2023 – Jun 2025
CVR College of Engineering India
Bachelor of Science in Electronics and Communications Aug 2018 – Mar 2022
Experience
Fidelity Investments Raleigh, NC, USA
Data Engineer Jun 2024 – Aug 2024
- Optimized existing PySpark financial processing workflows on AWS EMR by refactoring data structures and implementing DataFrame optimizations, reducing execution time by 60% while maintaining data integrity
- Evaluated AWS Neptune Graph Database feasibility against existing relational implementations.
- Implemented serverless APIs using AWS API Gateway and Lambda functions, while conducting comprehensive load testing for 25+ internal APIs using performance testing tools to validate scalability
- Developed and maintained data pipelines using Apache Airflow, creating DAGs with proper task dependencies
Infosys India
Data Engineer (Client: Caterpillar) Aug 2022 – Aug 2023
- Built end-to-end data pipelines with PySpark and SQL to ingest, clean, and transform 10M+ daily supplier shipment and inventory records, ensuring data consistency and integrity across systems.
- Implemented real-time data streaming using Apache Kafka, integrating supplier EDI feeds and API data into
Snowflake for near real-time analytics.
- Automated ETL orchestration using Apache Airflow (40+ DAGs), including retry logic, SLA monitoring, and alerting, achieving 99.5% pipeline reliability.
- Developed data validation and quality frameworks using PySpark and SQL to detect anomalies, enforce schema consistency, and ensure compliance with procurement standards.
- Implemented automated data quality monitoring and alerting frameworks within ETL pipelines, tracking schema changes, missing or duplicate records, and SLA breaches, reducing manual checks and data errors by 30%.
Catalog India
Data Engineer Jan 2021 – Aug 2022
- Developed Python + SQL ETL pipelines to ingest, clean, and transform blockchain transaction data.
- Built FastAPI microservices to ingest blockchain transactions into ETL pipelines for analytics.
- Orchestrated 10+ Airflow DAGs to automate ETL of multi-chain wallet logs, enabling near real-time analytics.
- Performed data aggregations on blockchain transactions using PySpark for batch analytics, generating insights
Technical Skills
Data Engineering: PySpark, SQL, Apache Kafka, Apache Airflow, ETL/ELT, Snowflake, Dimensional Modeling
Cloud: AWS (EMR, S3, Lambda), Terraform, Azure DevOps CI/CD
Programming: Python, Scala, Unix/Linux Scripting
Databases: PostgreSQL, MySQL, AWS Neptune Tools: dbt, Docker, Jenkins, Tableau, Grafana
Projects
Real-Time Stock Market Data Pipeline Using Apache Kafka, AWS, and Snowflake
∗ Implemented an end-to-end data engineering pipeline for real-time stock market data using Apache Kafka, AWS
EC2, AWS S3, and Snowflake.
∗ Established ETL processes to ingest and store streaming data into Snowflake’s cloud data warehouse via AWS S3
utilizing AWS EC2 instances for data processing and management.
∗ Optimized Snowflake database performance through effective data partitioning and clustering strategies
enhancing scalability and query speed.
Optimized Multi-API Data Pipeline Featuring Pydantic Validation and Low Latency
∗ Built a scalable, low-latency, fault-tolerant data ingestion pipeline using Prefect to orchestrate concurrent, reliable
extraction of JSON and CSV data from multiple diverse external APIs and sources.
∗ Applied Pydantic for strict schema validation and data parsing, optimizing throughput and minimizing latency
with asynchronous processing and error handling in Prefect. Integrated PostgreSQL for storage.
3. Software Engineer intern resume that passed Fetch and Snowflake
Real resumePassed the screen atSnowflake
Bachelor's in Computer Science & Data Science, Minor in Economic Analytics, University of Wisconsin - Madison, 2027
Show resumeHide resume
 View full size
Uploaded by its owner. Contact details redacted. What this resume does well
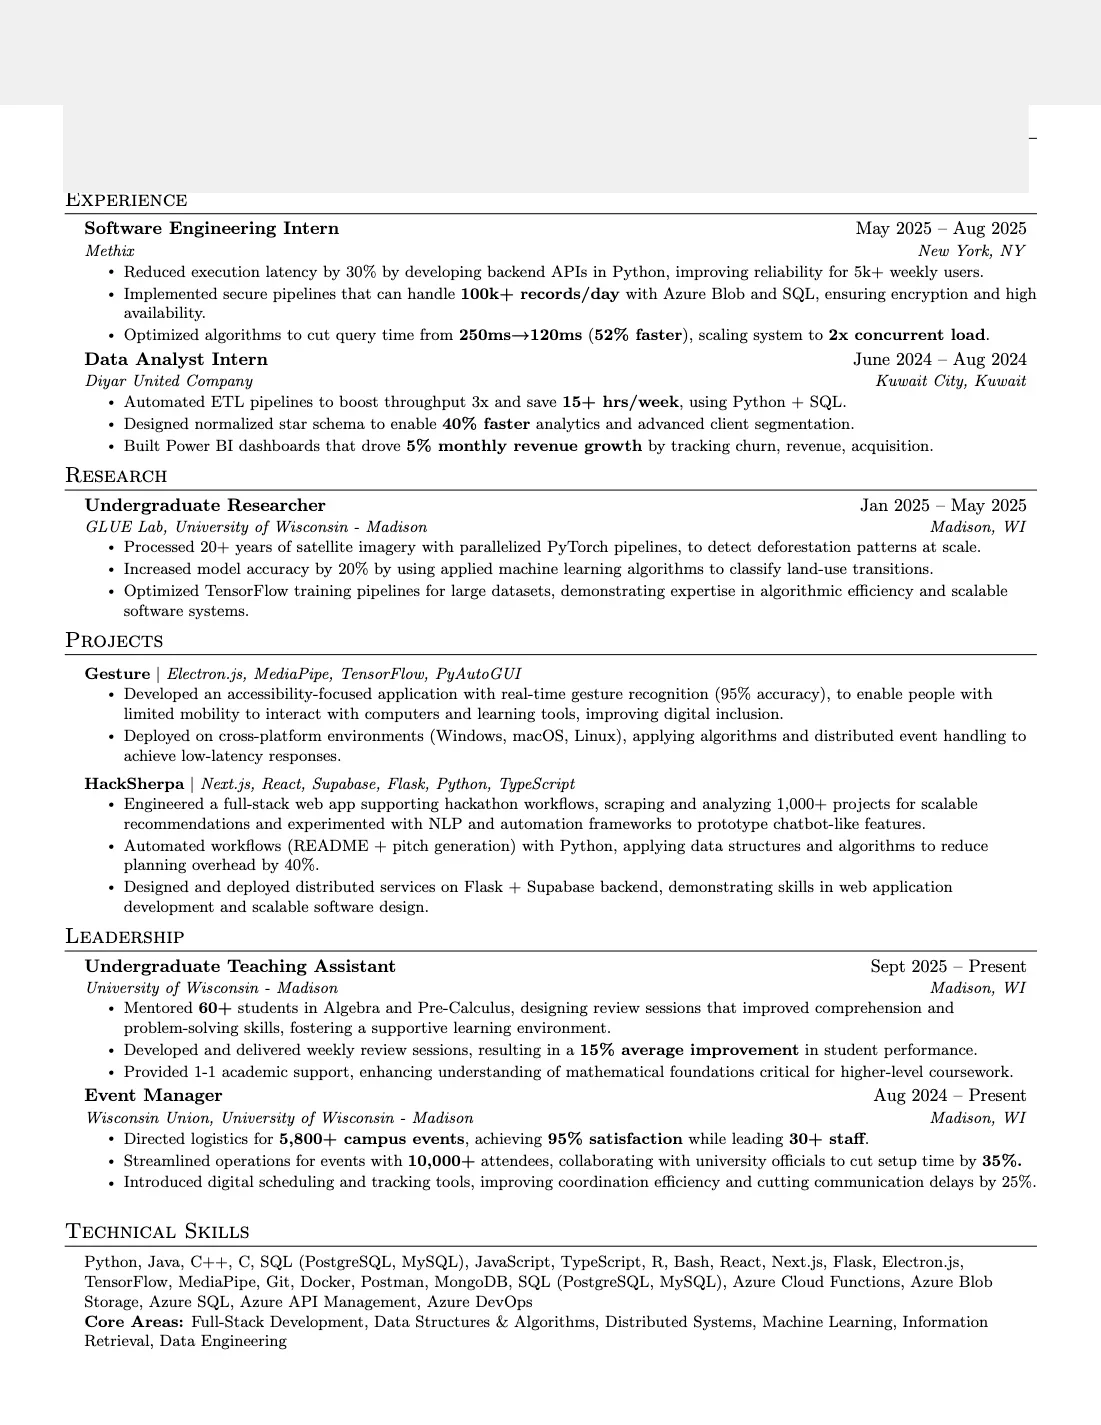
- Numbers in most bullet points17 of its 20 bullet points carry a figure, such as a percentage, a count or an amount.
- Education firstIt opens with education, the first thing a screener checks on a student resume.
- A projects sectionIt gives projects their own section, alongside 2 internships.
- 2 internshipsIt lists 2 internships among 5 roles, most recent first.
Read this resume as text
Education
University of Wisconsin - Madison Expected: May 2027
Bachelor of Science in Computer Science & Data Science, Minor in Economic Analytics (Dean’s List)
Experience
Software Engineering Intern May 2025 – Aug 2025
Methix New York, NY
- Reduced execution latency by 30% by developing backend APIs in Python, improving reliability for 5k+ weekly users.
- Implemented secure pipelines that can handle 100k+ records/day with Azure Blob and SQL, ensuring encryption and high availability.
- Optimized algorithms to cut query time from 250ms → 120ms ( 52% faster ), scaling system to 2x concurrent load .
Data Analyst Intern June 2024 – Aug 2024
Diyar United Company Kuwait City, Kuwait
- Automated ETL pipelines to boost throughput 3x and save 15+ hrs/week, using Python + SQL.
- Designed normalized star schema to enable 40% faster analytics and advanced client segmentation.
- Built Power BI dashboards that drove 5% monthly revenue growth by tracking churn, revenue, acquisition.
Research
Undergraduate Researcher Jan 2025 – May 2025
GLUE Lab, University of Wisconsin - Madison Madison, WI
- Processed 20+ years of satellite imagery with parallelized PyTorch pipelines, to detect deforestation patterns at scale.
- Increased model accuracy by 20% by using applied machine learning algorithms to classify land-use transitions.
- Optimized TensorFlow training pipelines for large datasets, demonstrating expertise in algorithmic efficiency and scalable software systems.
Projects
Gesture | Electron.js, MediaPipe, TensorFlow, PyAutoGUI
- Developed an accessibility-focused application with real-time gesture recognition (95% accuracy), to enable people with limited mobility to interact with computers and learning tools, improving digital inclusion.
- Deployed on cross-platform environments (Windows, macOS, Linux), applying algorithms and distributed event handling to achieve low-latency responses.
HackSherpa | Next.js, React, Supabase, Flask, Python, TypeScript
- Engineered a full-stack web app supporting hackathon workflows, scraping and analyzing 1,000+ projects for scalable recommendations and experimented with NLP and automation frameworks to prototype chatbot-like features.
- Automated workflows (README + pitch generation) with Python, applying data structures and algorithms to reduce planning overhead by 40%.
- Designed and deployed distributed services on Flask + Supabase backend, demonstrating skills in web application development and scalable software design.
Leadership
Undergraduate Teaching Assistant Sept 2025 – Present
University of Wisconsin - Madison Madison, WI
- Mentored 60+ students in Algebra and Pre-Calculus, designing review sessions that improved comprehension and problem-solving skills, fostering a supportive learning environment.
- Developed and delivered weekly review sessions, resulting in a 15% average improvement in student performance.
- Provided 1-1 academic support, enhancing understanding of mathematical foundations critical for higher-level coursework.
Event Manager Aug 2024 – Present
Wisconsin Union, University of Wisconsin - Madison Madison, WI
- Directed logistics for 5,800+ campus events, achieving 95% satisfaction while leading 30+ staff .
- Streamlined operations for events with 10,000+ attendees, collaborating with university officials to cut setup time by 35%.
- Introduced digital scheduling and tracking tools, improving coordination efficiency and cutting communication delays by 25%.
Technical Skills
Python, Java, C++, C, SQL (PostgreSQL, MySQL), JavaScript, TypeScript, R, Bash, React, Next.js, Flask, Electron.js
TensorFlow, MediaPipe, Git, Docker, Postman, MongoDB, SQL (PostgreSQL, MySQL), Azure Cloud Functions, Azure Blob
Storage, Azure SQL, Azure API Management, Azure DevOps
Core Areas: Full-Stack Development, Data Structures & Algorithms, Distributed Systems, Machine Learning, Information
Retrieval, Data Engineering
How to write a resume for Fetch, based on 3 that passed the screen
1. Put a number in your bullet points
Start each bullet with what you did and end with what came of it. A figure (users, latency, revenue, accuracy, time saved) makes the result concrete and easy to scan.
From the resumes above:
“Optimized existing PySpark financial processing workflows on AWS EMR by refactoring data structures and implementing DataFrame optimizations, reducing execution time by 60% while maintaining data integrity”Example 2
“Reduced execution latency by 30% by developing backend APIs in Python, improving reliability for 5k+ weekly users.”Example 3
Fetch resumes by the numbers
- By role:
- Software Engineer 100%
- By level:
- Full-Time 33%, Intern 33%, New Grad 33%
Based on 3 resumes, last updated Nov 19, 2026.